LexiSharp 0.7.0
dotnet add package LexiSharp --version 0.7.0
NuGet\Install-Package LexiSharp -Version 0.7.0
<PackageReference Include="LexiSharp" Version="0.7.0" />
<PackageVersion Include="LexiSharp" Version="0.7.0" />
<PackageReference Include="LexiSharp" />
paket add LexiSharp --version 0.7.0
#r "nuget: LexiSharp, 0.7.0"
#:package LexiSharp@0.7.0
#addin nuget:?package=LexiSharp&version=0.7.0
#tool nuget:?package=LexiSharp&version=0.7.0
LexiSharp





A composable information retrieval toolkit for .NET — build, measure and inspect search pipelines, from lexical BM25 to hybrid and reranked retrieval.
Index, retrieve, rank and judge a search pipeline: an in-memory inverted index, four ranking strategies and their BM25 variants, rank fusion, reranking, optional PostgreSQL backends, and model-agnostic seams for dense, learned-sparse and neural scoring — the models stay in your application. The core package references no NuGet package at all.
📖 Full documentation → — the guide, the
reference, and every measurement with the command that reproduces it. Published from
docs/; this README is the short version and the details are delegated to those
pages.
Install
dotnet add package LexiSharp # the core: index, scorers, engines, decorators — no dependencies
net10.0, MIT. Optional: LexiSharp.MessagePack (binary index persistence),
LexiSharp.AspNetCore (a GET /search minimal-API endpoint), LexiSharp.Postgres
(lexical, vector, sparse, fuzzy and true BM25 backends) — packages.
Use it
using LexiSharp.Core;
using LexiSharp.Indexing;
using LexiSharp.Ranking;

// Three pieces, one contract: the index owns the corpus statistics, the scorer is a pure
// ranking strategy reading from it, the engine orchestrates. Each of the three is an
// interface, so you replace one without touching the others.
ITextSearchEngine engine = new RankedTextSearchEngine(
    new InMemoryTextIndex(),
    new Bm25Scorer());

engine.Index(new[]
{
    new SearchDocument("1", "The search engine uses BM25 to rank the results"),
    new SearchDocument("2", "TF-IDF is a classic method of textual search"),
    new SearchDocument("3", "Italian cuisine is renowned in Rome"),
});

foreach (var result in engine.Search("textual search"))
    Console.WriteLine($"{result.DocumentId} - {result.Score:0.###}: {result.Document.Text}");
That is the smallest thing the library does. The rest is composition: every engine above
implements ITextSearchEngine, and a pipeline is stages wrapping each other. Given two
engines over one index, HashingEmbeddingProvider standing in for your
IEmbeddingProvider (no model, no service):
var hybrid = new HybridTextSearchEngine(
    new[] { lexical, dense },
    new ReciprocalRankFusionMerger());   // a BM25 score and a cosine, fused by rank, uncalibrated

ITextSearchEngine pipeline = new RerankedTextSearchEngine(
    hybrid, new ProximityReranker(index));   // ...or MMR, a cascade, MaxSim, a cross-encoder
Replacing a piece is the whole extension model — a PostgreSQL, vector, sparse or fuzzy
backend takes the same slot, and IEmbeddingProvider, ISparseEmbeddingProvider and
ICrossEncoderScorer are yours to implement: pipelines, and
backends.
LexiSharpIndex<T> is the typed facade over the same engine if you would rather hand it your
own objects — Getting started.
See it running
dotnet run --project samples/LexiSharp.Demo # → http://localhost:5000
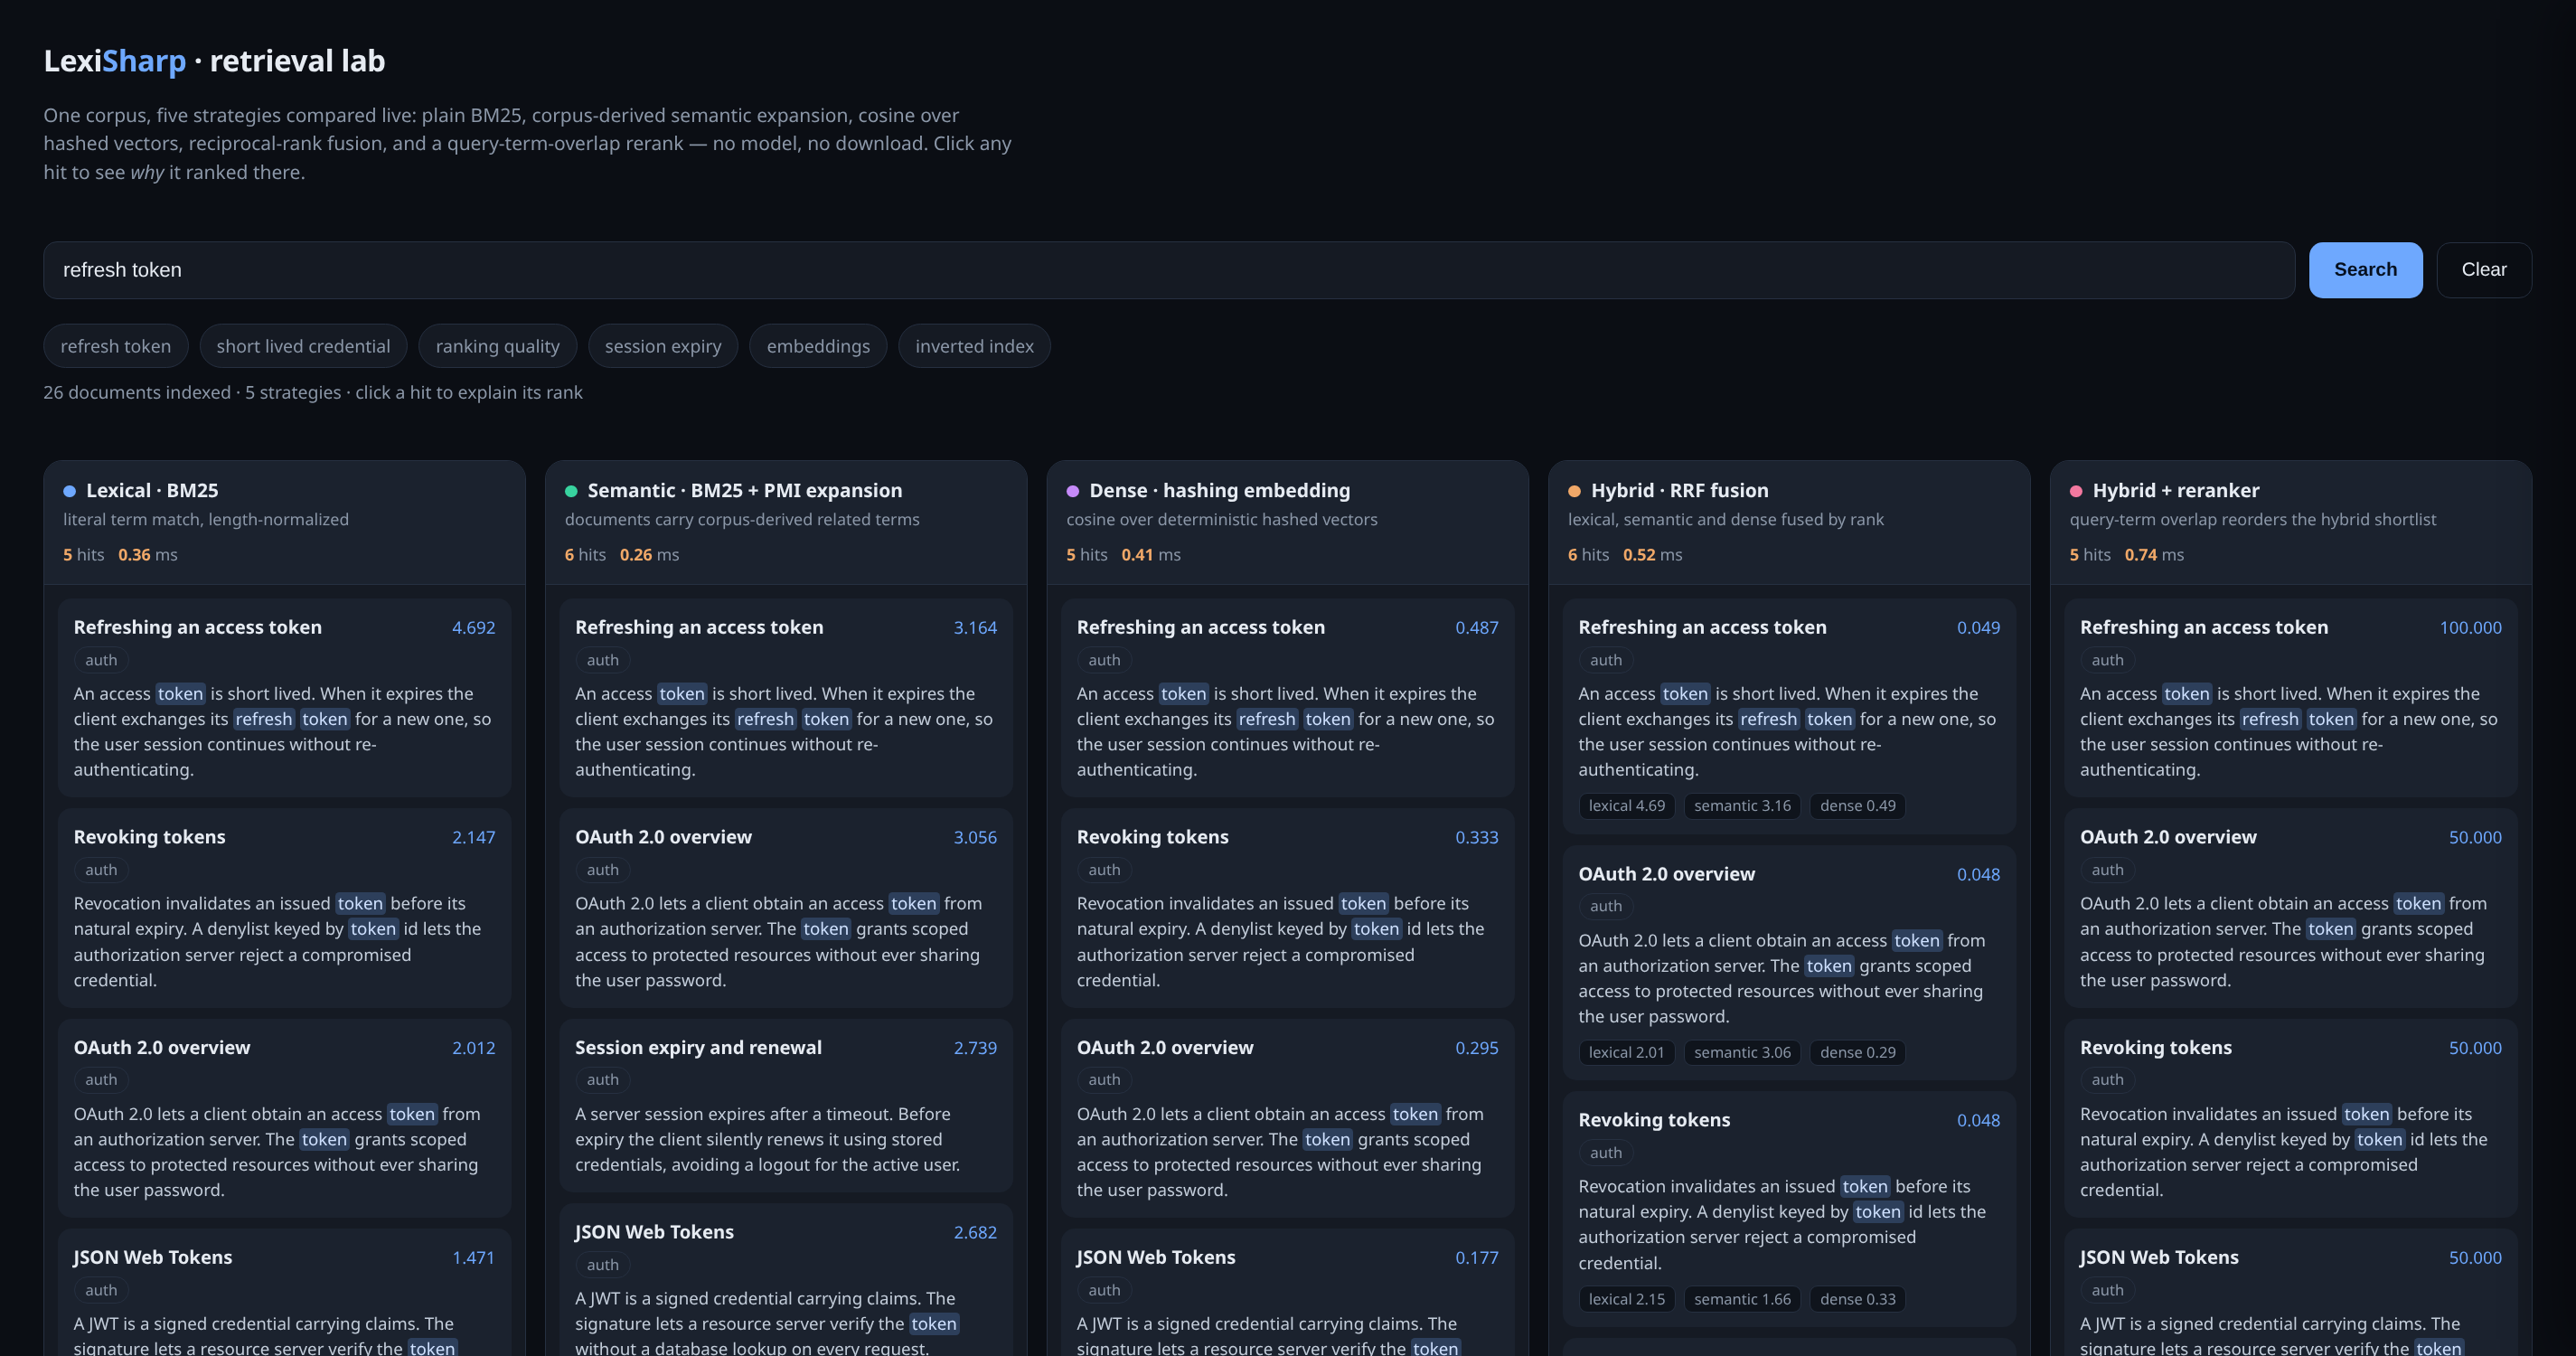
Five retrieval strategies over one corpus, compared live — BM25, corpus-derived semantic expansion, dense hashing embeddings, RRF fusion and a term-overlap rerank — with per-lane latency, highlighting and a click-through "why did this rank here?" panel. No model, no external service.
What it does not do
Stated plainly, so nothing is implied. The full list, with the measurement behind each claim, is Scope and limits.
- It matches the published BM25 baseline on two of the three corpora it can be compared on, and it
does not on the third. On NFCorpus and SciFact, with the analysis, the BM25 parameters and the
metric convention aligned to those the reference figures were produced with, the plain BM25 scorer
reaches nDCG@10 0.3215 and 0.6788 against 0.3218 and 0.6789 — equal to the fourth
decimal. On ArguAna, at the reference's own k1=0.9/b=0.4, it reaches 0.219 against the
0.3970 that implementation publishes, and the deficit is not accounted for. The same scores
read under the library defaults are 0.308 / 0.662 / 0.289; that difference is the analyzer, the
parameters and one task convention, not the ranking. Corpora are md5-verified on download, and the
numbers are pinned and re-checked by the
Pinned referenceworkflow, which replays every pinned configuration and exits non-zero on drift. It runs on a dispatch, on a push that touches the library or the harness, and weekly — see evaluation. - A quality claim this repository withdrew, before publishing it. It reported 0.4061 on
ArguAna, above the published 0.3970, and attributed the gap to query-term scoring: the library
deduplicated query terms, the reference counts them, and counting them was said to be worth
+0.0705. Measured, the setting is worth +0.052 (0.219 to 0.271 at matched parameters) and the
0.4061 is not reproducible by any code path. The figures could not have come from the code that
cited them, which deduplicated the query before the scorer could see a repetition. Neither the
claim nor the setting is in the
v0.6.0tag —git tag --containsfinds none — so no release carried either. The measurement and the reasoning are in evaluation and inQueryTermWeighting. - No scorer here has a measured win over a tuned BM25. BM25+ and BM25L, tuned on their own
δ, tie a tuned BM25 on the reference corpus and NFCorpus and edge it by 0.002–0.004 on SciFact — an in-sample margin, so an upper bound rather than a result. On ArguAna, untuned, they lose, and noδ-tuned ArguAna row exists, so whether tuning closes that gap is unmeasured (ranking). - The SQL backends' retrieval quality is unmeasured. The BEIR numbers come from the in-memory engines; the live integration tests cover schema, query paths and cosine behaviour, not relevance (backends).
- Not every combination is tested. Engines, scorers, rerankers and mergers are tested individually and in the combinations described, but not every pairing — treat an unusual one as supported but unproven until you test it on your data.
- Version 0.6.0, one maintainer. The public API may still change between minor versions — pin a version and read the release notes.
Development
dotnet build LexiSharp.slnx
dotnet test  tests/LexiSharp.Tests   # xUnit suite; the Postgres suites need POSTGRES_TEST_CONNECTION
The retrieval quality gate replays every pinned configuration on the three BEIR corpora and exits non-zero on any drift. It downloads the corpora on first run, so it is not part of the xUnit suite:
dotnet run --project bench/LexiSharp.Eval -c Release -- --verify-reference
Benchmarks, the evaluation harness and the behavioural gate: Reference and Benchmarks.
License
MIT — see LICENSE. The ParadeDB pg_search extension used by the BM25 backend is
licensed separately, under AGPL-3.
| Product | Versions Compatible and additional computed target framework versions. |
|---|---|
| .NET | net10.0 is compatible. net10.0-android was computed. net10.0-browser was computed. net10.0-ios was computed. net10.0-maccatalyst was computed. net10.0-macos was computed. net10.0-tvos was computed. net10.0-windows was computed. |
-
net10.0
- No dependencies.
NuGet packages (3)
Showing the top 3 NuGet packages that depend on LexiSharp:
| Package | Downloads |
|---|---|
|
LexiSharp.MessagePack
MessagePack persistence for the LexiSharp in-memory text index: save and reload a full corpus as compact binary. |
|
|
LexiSharp.AspNetCore
ASP.NET Core integration for LexiSharp: a minimal-API search endpoint on top of LexiSharpIndex<T>. |
|
|
LexiSharp.Postgres
PostgreSQL backends for LexiSharp: lexical full-text search on tsvector, ANN on pgvector, sparse retrieval, fuzzy search on pg_trgm, and true Okapi BM25 on the ParadeDB pg_search (Tantivy) extension. |
GitHub repositories
This package is not used by any popular GitHub repositories.